Abstract
Everyone is keen to know when a recession has started, but official announcements come only after several months, and real-time detection methods typically struggle—as the Great Recession showed. These methods face two challenges. First, they rely on data that are later significantly revised (such as GDP), so they only have a muddied view of the situation in real time. Second, they optimize in-sample performance, but this does not guarantee out-of-sample results. This paper proposes an algorithm that addresses both. First, it detects recessions from data on labor market slack—unemployment and vacancy rates—which are barely revised. Second, it selects recession classifiers for out-of-sample performance, using pseudo-out-of-sample tests on past recessions. Placed in the shoes of the NBER Business Cycle Dating Committee, the algorithm issues an early warning 5.2 months before the NBER announcement on average over the 6 recessions since 1978, and it reaches a 100% recession probability before the announcement or in the same month in 5 of them. The algorithm produces only one false positive out of sample: it takes the 2023–2024 labor market slowdown for a recession. Trained on the data between April 1929 and December 2025, the algorithm gives a recession probability of 0% in August 2026.
Figure 5D: Out-of-sample recession probability during the Guld War recession
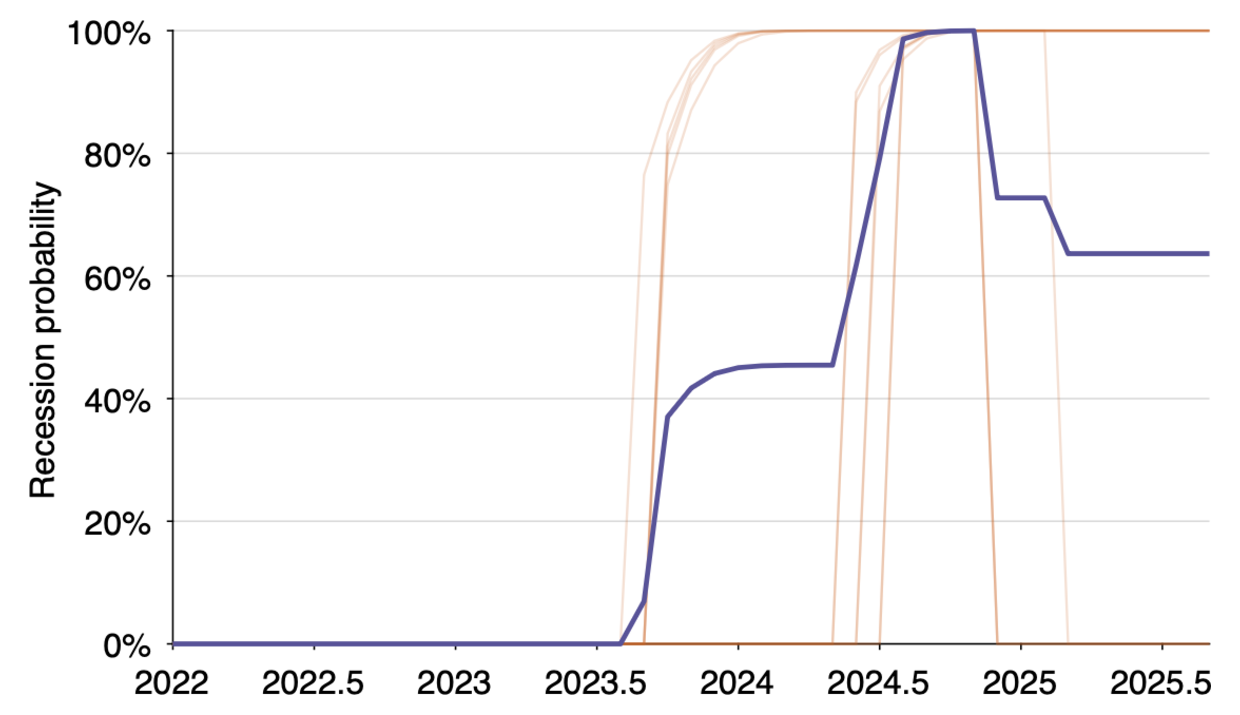
Figure 6D: Out-of-sample recession probability during the dot-com recession

Figure 7D: Out-of-sample recession probability during the Great Recession

Figure 8D: Out-of-sample recession probability during the pandemic recession

Citation
Michaillat, Pascal. 2026. “Learning to Detect Recessions from Pseudo-out-of-sample Tests.” arXiv:2506.09664v5. https://doi.org/10.48550/arXiv.2506.09664.
@techreport{M26,
author = {Pascal Michaillat},
year = {2026},
title = {Learning to Detect Recessions from Pseudo-out-of-sample Tests},
number = {arXiv:2506.09664v5},
doi = {https://doi.org/10.48550/arXiv.2506.09664}}